How many proteins are there?
Humans have about 20,000 protein-coding genes, but counting protein sequences, molecular forms, or copies gives different answers.
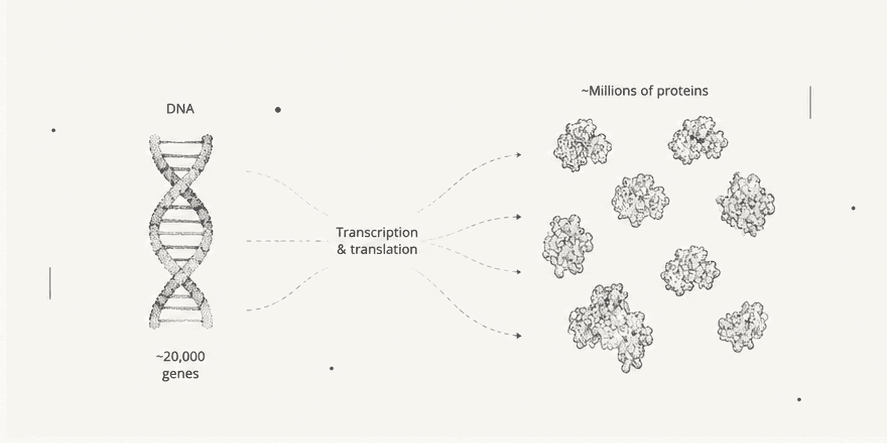
Humans have about 20,000 protein-coding genes, but there is no single total for the proteins they produce. One gene can give rise to several amino acid sequences, and each sequence can occur in different molecular forms. Counting every physical copy inside a cell gives a much larger number again.
These distinctions explain why answers range from thousands to billions. There is also a difference between sequences annotated in a genome and proteins demonstrated experimentally. To examine that gap, we compared published peptide observations with human reference sequences. The results help explain why a count of annotated proteins is easier to obtain than a complete inventory of the proteins our cells produce.
How many different proteins do humans have?
GENCODE v50 reports 19,442 human protein-coding genes and 172,117 distinct annotated translations. Its statistics cover the main chromosomes; the headline gene count excludes 665 readthrough genes, which span neighboring gene loci.[1]
A translation is the amino acid sequence assigned to a coding transcript. Different transcripts can encode the same sequence, so the number of transcripts is larger than the number of distinct translations. These are annotation counts, not experimental confirmation that every sequence exists as a stable protein.
| Annotation level | GENCODE v50 count | What is counted |
|---|---|---|
| Protein-coding genes | 19,442 | Gene loci under the release's headline counting rules |
| Distinct translations | 172,117 | Different annotated amino acid sequences |
| Protein-coding transcripts | 278,455 | RNA transcript models, including full and partial coding sequences |
The roughly 70,000 protein sequences cited in the 2018 review by Aebersold and colleagues came from an older Ensembl annotation. Comparing that figure with a newer release requires attention to annotation coverage and definitions; it does not mean humans recently acquired thousands of new genes.[3]
How many annotated protein variants have been observed?
There is no complete experimental count of human protein variants that corresponds directly to the 172,117 annotated translations above. In our reanalysis of a published splice-event table, 95.6% of 46,720 observed peptide sequences matched more than one GENCODE v50 reference sequence. The result illustrates one obstacle to such a count: detecting a protein fragment often leaves the identity of the complete sequence unresolved.
Many proteomics experiments cut proteins into short fragments called peptides and identify them by mass spectrometry. A peptide can reveal a region created by alternative splicing while occurring in several protein variants that differ elsewhere. Evidence for that region therefore does not necessarily distinguish one complete variant.[4]
| Matching result for an observed peptide | Distinct peptide sequences | Share of the 46,720 peptides |
|---|---|---|
| Matches multiple reference sequences | 44,655 | 95.58% |
| Matches exactly one reference sequence | 2,038 | 4.36% |
| No matching reference sequence | 27 | 0.06% |
For example, all 15 APP-associated peptide sequences in our extraction individually matched multiple reference sequences. Their ambiguity does not invalidate the original evidence for local splicing events. Several shared peptides considered together can sometimes distinguish a variant; our analysis assessed individual peptides and did not perform that combined inference.
The pattern persisted under narrower counting rules. Among 30,268 peptides at least nine amino acids long with at least two spectra in one table entry, 96.4% matched multiple reference sequences. Restricting the competing reference set to full-length protein-coding models on the main chromosomes still left 94.4% of the original peptides with multiple matches.
These results explain a measurement limitation, but cannot establish what fraction of all human protein variants has been observed. We used the table's event-associated peptides, not every peptide from the study or only its restricted splice-junction subset. A reference sequence without a peptide match in this selected table may have evidence elsewhere. We also did not reanalyse the spectra or recalculate identification error rates.
How many human protein forms are there?
Even identifying every amino acid sequence would not give a complete count of human proteoforms, whose total remains unknown. A proteoform is a specific molecular form of a protein, defined by its sequence and modifications. Alternative splicing, inherited sequence differences, cleavage, and chemical modifications such as phosphorylation can all produce different forms.[3]
This is why gene counts cannot settle the size of the human proteome. Aebersold and colleagues discussed one million proteoforms in a cell type as a possible mapping depth, rather than an established census. Counts across tissues, individuals, and biological conditions have a broader scope than counts within one cell type.
Theoretical combinations also exceed the forms that biology actually produces. A protein with several modifiable sites need not occur in every possible combination. The fragment-matching problem above also extends to modifications: identifying modified peptides does not necessarily establish which modifications coexist on the same intact molecule.[3]
How many proteins are in a cell?
Counting physical protein molecules asks a different question from counting sequences or forms: each copy contributes to the total. A 2023 analysis by Dolgalev and colleagues integrated copy-number estimates for 12,653 canonical proteins in HeLa cells, totaling approximately 3.36 billion molecules per cell. The first number counts protein identities; the second counts their physical copies. HeLa is a cultured human cancer cell line, not a reference for every human cell.[7]
| Cell system | Canonical proteins in the integrated map | Estimated molecules per cell |
|---|---|---|
| Escherichia coli | 3,852 | 5,852,319 |
| Budding yeast, Saccharomyces cerevisiae | 4,680 | 81,627,580 |
| HeLa | 12,653 | 3,360,824,528 |
The authors selected seven studies per system, normalized abundance estimates using literature values for protein mass per cell, and averaged copy numbers. Original study totals differed by up to tenfold. These estimates therefore depend on calibration, growth conditions, and which proteins were detected.[7]
Protein identities and copies answer different questions. Neither table column counts all modified proteoforms, and a population-based estimate does not specify the inventory of an individual cell.
How many protein sequences have been catalogued?
UniProtKB release 2026_03, dated September 2, 2026, contains 150,006,383 records across organisms. These entries document protein sequences and their annotations; they do not enumerate all proteins that exist in nature.[8]
| Database section | Records in release 2026_03 | Annotation status |
|---|---|---|
| Swiss-Prot | 575,748 | Manually reviewed |
| TrEMBL | 149,430,635 | Unreviewed, with computational annotation |
| UniProtKB total | 150,006,383 | Both sections combined |
X-Total-Results response header and the release in X-UniProt-Release; each response requests only one example entry.[8][9][10]The distinction between annotation and observation also applies to these database totals. Reviewed status describes curation, not necessarily direct experimental observation of the protein. UniProt separately records evidence for protein existence, including protein-level evidence, transcript-level evidence, and inference from related sequences.[9]
An entry is also not always one unique amino acid sequence. UniProt can group alternative isoforms within an entry, while separate entries can represent proteins from different organisms. Consequently, an entry count cannot be substituted for a count of unique sequences, genes, or proteoforms.[11]
How many protein types exist across all life?
There is no established census of protein types across all life. The often-quoted estimate of about 50 billion comes from a 2005 Berkeley Lab article, which based it on the number of known life forms. The article does not provide enough calculation detail to treat this as a reproducible modern estimate.[12]
Even a comprehensive sequence collection would need a counting rule: identical sequences shared by organisms, sequence variants, and chemically modified forms could each be grouped or counted separately. The proteome sizes of individual species address a narrower question with a more clearly defined denominator.
For a citable number, retain the scope and date alongside the value. A gene annotation count describes coding potential, a cellular copy count describes abundance, and a database total describes the contents of a particular release.
Methods and data
We analysed Supplementary Table 3 from Sinitcyn and colleagues' 2023 deep proteome sequencing study, which associates peptides with splicing events in six human cell lines. We extracted distinct peptide sequences with positive spectrum counts and searched them against 241,765 distinct sequences in the full GENCODE v50 translation file. This broad reference set includes partial models and alternative loci as possible competing matches, so it differs from the headline annotation count. We treated isoleucine and leucine as indistinguishable when matching peptides.[4][5][6]
Our methods and reproduction instructions document the reference definitions, sensitivity checks, and exclusion of 40 spreadsheet cells whose peptide and spectrum-count lists could not be paired reliably. The input provenance, analysis code, peptide-level results, and reference-sequence results make the comparison available for inspection and reuse.