Predict biomolecular complex structures and binding affinities for proteins, ligands, DNA, and RNA.
Predict biomolecular complex structures and binding affinities for proteins, ligands, DNA, and RNA.
Boltz-2 predicts all-atom 3D structures for biomolecular complexes and estimates binding affinity for protein-small-molecule interactions. The ProteinIQ webserver accepts sequences, ligands, templates, and optional constraints, then returns predicted structures, confidence metrics, and downloadable result files. It supports protein-ligand cofolding, protein complex prediction, protein-DNA and protein-RNA modeling, affinity prioritization, and template- or constraint-guided prediction.
Boltz-2 (Passaro et al. 2025) is the successor to Boltz-1 (Wohlwend et al. 2024) and adds a separate affinity module for protein-small-molecule complexes. Boltz-1 remains available under Model version for structure-only runs.
Boltz-2 jobs start at 50 credits. The calculator scales mainly with the number and length of input molecules, inference settings, and requested samples, while additional samples have a smaller incremental effect. The exact credit price is calculated before submission.
ProteinIQ displays chain IDs for constraint definitions and template mappings. A job must include at least one protein, DNA, or RNA chain; ligands, templates, and precomputed MSAs cannot be submitted by themselves. The total number of residues across all inputs is limited to 5,000, and each small-molecule ligand is limited to 300 heavy atoms.
| Input | Accepted formats | Limits and behavior |
|---|---|---|
| Protein | FASTA or FA text, .fasta or .fa file, .pdb file, or RCSB chain | Up to 10 protein inputs, one FASTA record each; files up to 50 MB. RCSB fetches require a chain specifier. Protein sequences use single-letter residues. Query PDBs must contain one protein chain and one model, without insertion codes or modified residues. For these cases, submit exact FASTA sequences with residue modifications. Query PDB coordinates are not used as templates. |
| MSA | A3M or native paired CSV text, .a3m or .csv file | Up to 10 MSAs; files up to 50 MB. Each alignment is assigned to protein chains in submission order. |
| Ligand | SMILES text, .smi or .smiles file, .sdf, .mol, or .mol2 file, or a PubChem record | Up to 10 ligands, one molecule per file; files up to 10 MB. Each ligand can contain at most 300 heavy atoms. Use a protein chain instead of a ligand input for peptide ligands. |
| CCD ligand | One CCD code such as ATP, NAD, HEM, or SAH | Up to 10 CCD ligands. Codes are 1-5 alphanumeric characters. This input accepts CCD codes, not custom SMILES or structure files. |
| DNA | FASTA or FA text, .fasta or .fa file | Up to 10 DNA molecules, one FASTA record each; files up to 10 MB. |
| RNA | FASTA or FA text, .fasta or .fa file | Up to 10 RNA molecules, one FASTA record each; files up to 10 MB. |
| Template | .pdb or .cif file, or an RCSB structure | Up to 5 templates; files up to 50 MB. CIF and mmCIF templates must include full metadata. Templates act as structural guides and can be assigned to query chains with the template settings below. |
| Job name | Text | Optional label used to identify the run. |
Boltz input files (YAML and complete-complex FASTA documents) are temporarily unavailable for new runs. Add each molecule using the Protein, DNA, RNA, Ligand or CCD ligand inputs. Add alignments and structural guides using the MSA and Template inputs. Ordinary FASTA sequence uploads remain available. Existing jobs retain their input files and results.
The settings below cover prediction, MSA generation, affinity estimation, diagnostics, constraints, templates, and per-molecule controls. Defaults and ranges follow the current Boltz-2 webserver definition. Some advanced fields appear only when their parent option is enabled; unset optional fields use the native model defaults.
| Setting | Default or range | Description |
|---|---|---|
| Number of samples | 1; 1-20 | Number of independent structure samples to generate. |
| Recycling steps | 3; 1-10 | Number of recycling iterations during structure inference. |
| Sampling steps | 200; 50-500 in 10-step increments | Number of diffusion sampling steps for structure inference. |
| Step scale (temperature) | Native default; 1.0-2.0 in 0.05 steps | Sampling temperature or step scale. When not set, the native default is 1.5 for Boltz-2 and 1.638 for Boltz-1. |
| Output format | CIF | Predicted structures can be returned as CIF or PDB files. CIF is the recommended format. |
| Setting | Default or range | Description |
|---|---|---|
| Generate MSA | Off | Generates an MSA with ColabFold for supported protein inputs. It can improve accuracy but increases runtime. |
| MSA depth | Normal; Shallow 2048, Normal 8192, Deep 16384 sequences | Limits alignment sequences used by the model for uploaded or generated MSAs. Choose Custom maximum to use Max MSA sequences. This controls model input depth, not server search depth. |
| MSA pairing strategy | Greedy | Selects Greedy or Complete pairing for paired MSAs. |
| Max MSA sequences | 8192; 512-16384 in 512-sequence steps | Sets the maximum MSA size. MSA depth overrides this value when a depth preset is selected. |
| Subsample MSA | Off | Subsamples a large MSA to reduce runtime. |
| Subsampled sequences | 1024; 256-4096 | Number of sequences retained when MSA subsampling is enabled. |
| MSA server URL | Not set | Optional custom endpoint for MSA generation. When not set, the default ColabFold endpoint is used. |
| MSA server username | Not set | Optional basic-auth username for a custom MSA server. Use it together with an MSA server password. |
| MSA server password | Not set | Optional basic-auth password for a custom MSA server. Use it together with an MSA server username. |
| MSA API key header | Not set | Optional header name for token authentication with a custom MSA server. Use it with an API key value. |
| MSA API key value | Not set | Optional API token for a custom MSA server. Do not combine token authentication with username and password authentication. |
| Setting | Default or range | Description |
|---|---|---|
| MW-corrected affinity | Off | Applies a molecular-weight correction when comparing affinity predictions for ligands of different sizes. |
| Binding affinity | Predict when supported | Choose Structure only to disable affinity while retaining ligand structure prediction. |
| Affinity ligand chain | First ligand | Optional chain ID shown beside a ligand. Only the selected ligand must be unique; duplicate cofactors do not disable its affinity calculation. Disconnected SMILES retain all components but skip affinity. |
| Affinity sampling steps | 200; 50-500 in 10-step increments | Number of diffusion sampling steps used for affinity prediction. |
| Affinity samples | 5; 1-20 | Number of diffusion samples used for affinity prediction. |
| Save PAE matrix | Off | Writes the full predicted aligned error matrix to the result files. |
| Save embeddings | Off | Writes native single and pair representations to an NPZ file. Pair representations can be large. |
| Save PDE matrix | Off | Writes the full predicted distance error matrix to the result files. |
| Random seed | Not set; integer 0-4294967295 | Leave empty for native random seeding. Zero is a valid fixed seed. API requests must use a JSON number, not a string. |
| Model version | Boltz-2 | Selects Boltz-2 or the legacy Boltz-1 structure-only model. |
| Method conditioning | None | Optional experimental-method conditioning for Boltz-2, using any method type Boltz accepts, such as X-ray diffraction, cryo-EM, solution NMR, MD, AlphaFold DB or Boltz-1. None disables method conditioning. |
| Setting | Default or range | Description |
|---|---|---|
| Use constraint potentials | Off | Constraints are passed to inference either way. When enabled, force=true in pocket or contact constraints adds an inference-time potential; covalent bonds do not use this force flag. |
| Pocket constraints | Not set | Format: binder|contacts|max_distance|force. Example: C|A:45,A:46|6.0|true. Omitted distance defaults to 6 Å and omitted force to false. The force field is strict only when constraint potentials are enabled. |
| Covalent bonds | Not set | Format: chain:residue:atom,chain:residue:atom. Example: A:12:SG,B:1:C22. Supports canonical protein, DNA, and RNA residues plus CCD ligand; custom SMILES, MOL, SDF, and MOL2 ligands are not supported here. |
| Contact constraints | Not set | Format: chain:residue,chain:residue|max_distance|force. Omitted distance defaults to 6 Å and omitted force to false. The force field is strict only when constraint potentials are enabled. |
| Enforce template backbone | Off | Applies a template backbone constraint during inference. |
| Template deviation threshold (Å) | 2.0 Å; 0.5-5.0 Å | Maximum allowed template deviation when Enforce template backbone is enabled. |
| Template chain mapping | Not set | Assigns templates to query chains, one mapping per line. Template indices start at 0 in upload order. Example: 0:A,B applies the first template to query chains A and B. Leave blank for automatic matching. |
Per-template options (JSON) accepts an array in upload order, for example [{"chain_id":["A"],"template_id":["B"],"force":true,"threshold":2}]. Here chain_id selects query chains and template_id selects source template chains. Supply equal-length arrays. Each object overrides the corresponding global options. PDB templates require SEQRES records; coordinate-only PDB exports are insufficient.
To add a template, choose More → Template → Upload and select a PDB or CIF file. Open Template options to assign it to the query chain IDs shown beside the molecule labels. For example, with two protein chains A and B and one uploaded template, enter 0:A,B. Enable Enforce template backbone only when you want the template constraint, then set its deviation threshold in Å.
| Setting | Default or range | Description |
|---|---|---|
| Copies | 1; 1-10 | Available for proteins, ligands, CCD ligand, DNA, and RNA. Copies duplicate a molecule and assign separate chain IDs. |
| Cyclic | Off | Available for protein, DNA, and RNA inputs. Marks the molecule as head-to-tail cyclic. |
| Residue modification | None; up to 10 per molecule | Available for protein, DNA, and RNA inputs. Each modification uses a residue position and a CCD code, with no more than one modification at the same position. |
A default run generates one sample with automatic MSA generation off, 3 recycling steps, 200 structure and affinity sampling steps, CIF output, and no confidence filter, diagnostic matrices, or constraints. Adjust the number of samples before increasing low-level sampling settings when the goal is to compare alternative predictions.
Three presets cover the usual starting points. Default runs one sample without a generated MSA, With MSA adds a ColabFold alignment, and Thorough combines the alignment with 5 samples and 10 recycling steps, as in AlphaFold3.
Without Generate MSA or an uploaded MSA, protein chains run in single-sequence mode, which the Boltz documentation does not recommend because it reduces accuracy. A single-sequence run is still a cheap way to confirm that chains, ligands and chain IDs are right. For a natural protein with known homologs, repeat it with Generate MSA at Normal depth before interpreting the result; designed and orphan proteins often gain little from an alignment.
One sample is enough to test an input; 3 to 5 suit a result that will be interpreted, because they show whether the fold, interface and ligand pose recur. Lower Step scale (temperature) values make samples more diverse. Change recycling, sampling and affinity step settings only as a deliberate comparison with a default run.
A poorly matched template biases the result toward its own fold, so run an untemplated control when its relevance is uncertain. Pocket and contact constraints are only hints unless force is true and Use constraint potentials is on. A covalent bond is an input assumption, not a prediction that the reaction occurs.
To compare a ligand series, keep the protein sequence, MSA choice, templates, constraints, sampling settings and Random seed identical across jobs, and place the compound to be scored first or name it in Affinity ligand chain. Strip counterions first: a disconnected SMILES, one containing ., receives no affinity.
Each run opens in the structure viewer and includes data and file views for inspecting metrics and downloading results. The available outputs depend on the selected model, inputs, samples, and diagnostic settings.
| Output | Description |
|---|---|
| Predicted structures | Every requested CIF or PDB sample, retaining native filenames and numeric rank. Rank 0 in a native filename is displayed as rank 1. Ordering follows native structure confidence, including runs with affinity. |
| 3D structure viewer | Interactive inspection of the predicted complex and its chains. |
| Confidence metrics | Overall confidence, local confidence, pTM, and ipTM metrics where applicable. |
| Binding probability | affinity_probability_binary for protein-small-molecule complexes; this is a model prediction, not an experimental measurement. |
| Affinity estimate | affinity_pred_value for protein-small-molecule complexes, reported as a predicted log10(IC50) in micromolar units. More negative values indicate stronger predicted binding within a comparison set. |
| Error matrices | PAE and PDE matrices when the corresponding full-matrix settings are enabled. |
| Downloadable files | All structures, full confidence and affinity JSON, per-token pLDDT NPZ, selected matrices and embeddings, generated MSA CSV, the native input YAML and its assets, processed manifest/record JSON, and the curated run log. |
Affinity is one estimate for the run, evaluated from the native rank-0 complex. It is shown with that prediction and preserved in the full affinity JSON, including individual ensemble heads. It is not an independent score for every sampled pose, so in the Data view only the rank 1 row carries affinity values. Workflow outputs include predicted structures, PAE matrices, prediction metrics and supporting files.
Read a result in three passes: the structure, then the confidence metrics, then affinity. Affinity is computed from the predicted rank 1 pose, so a strong affinity value on an implausible pose is weak evidence.
Boltz reports confidence on a 0 to 1 scale. A complex_plddt of 0.96 corresponds to 96 on the 0 to 100 scale AlphaFold uses for pLDDT. pTM, ipTM and PAE mean the same here as in other predictors, and structure prediction confidence covers reading them together.
| Field | Meaning |
|---|---|
confidence_score | Native ranking score, 0.8 * complex_plddt + 0.2 * iptm, with ptm in place of iptm for a single chain. It orders samples within one job and is not a probability of being correct. |
complex_plddt, complex_iplddt | Mean local confidence over the complex, and the same average with interface tokens upweighted. |
ptm, iptm | Predicted TM-score for the whole complex and for its interfaces. |
ligand_iptm, protein_iptm | ipTM over protein-ligand interfaces only and over protein-protein interfaces only. protein_iptm is 0 when the job has one protein chain, because no such interface exists. |
complex_pde, complex_ipde | Predicted distance error in Å over the complex and at interfaces. Lower is better. |
chains_ptm, pair_chains_iptm | Per-chain pTM and per-chain-pair ipTM in the confidence JSON, keyed by chain index from 0 in chain-ID order. |
A high complex_plddt does not show that chains or a ligand are placed correctly; iptm, ligand_iptm and the cross-chain PAE blocks answer that. With Save PAE matrix on, the PAE NPZ, confidence JSON and pLDDT NPZ can be scored in ipSAE, which scores only residue pairs with low PAE, so disordered regions do not drag it down as they do ipTM.
| Field | Meaning |
|---|---|
affinity_probability_binary | Probability from 0 to 1 that the ligand is a binder rather than a decoy. Intended for hit discovery across diverse compounds. |
affinity_pred_value | Predicted affinity as log10(IC50), with IC50 in µM. Lower is stronger. Intended for ranking active compounds during hit-to-lead and lead optimization. |
affinity_pred_value1, affinity_pred_value2, affinity_probability_binary1, affinity_probability_binary2 | Predictions of the two ensemble models behind the main values, in the downloaded affinity JSON. Large disagreement marks a less stable estimate. |
The concentration is 10 raised to affinity_pred_value, in µM, and the pIC50 is 6 - affinity_pred_value. The KRAS example below returns -0.401, about 0.40 µM or a pIC50 of 6.4. The Boltz documentation also gives (6 - affinity_pred_value) * 1.364 for a kcal/mol scale on which higher means stronger.
affinity_pred_value | IC50 |
|---|---|
-3 | 1 nM |
-2 | 10 nM |
-1 | 100 nM |
0 | 1 µM |
1 | 10 µM |
2 | 100 µM |
The value is not an experimental Kd or IC50. The affinity head was trained on IC50, Ki, Kd and similar measurements placed on one log scale (Passaro et al. 2025), so it behaves as an IC50-like score for ordering related active compounds on one target under identical settings. The Boltz documentation advises against using it to separate actives from inactives, which is the job of affinity_probability_binary.
That probability has no universal cutoff, and a threshold that works for one target may not transfer to another. Passaro et al. found that affinity accuracy varied widely between targets and assays, so score a few compounds with known activity on the target before trusting a ranking of unknown ones.
Affinity covers one ligand only: the first ligand, or the chain named in Affinity ligand chain. Cofactors, ions and other ligands shape the structure but receive no score, and there is no affinity for protein-protein, protein-DNA or protein-RNA binding. A wrong pocket or pose makes the value meaningless, however confident the structure.
A run returns no affinity when Binding affinity is Structure only, Model version is Boltz-1, or the job has no small-molecule ligand. With automatic selection, affinity is also skipped, with the reason recorded in the result, when the first ligand appears more than once, is a disconnected SMILES, is a multi-residue CCD sequence, or has more than 128 atoms. The structure is still predicted in each case.
An explicitly selected ligand with copies is rejected before submission. Ligands well above 56 atoms can be scored but fall outside the size range the Boltz documentation recommends for affinity.
Agreement on fold, interface and ligand pose across 3 to 5 samples is better evidence than one high confidence_score. Measure each pocket, contact and covalent constraint in the structure to confirm it was satisfied, including forced ones.
For ligand complexes, PoseBusters checks bond geometry, stereochemistry and clashes once the ligand pose and receptor are saved as separate files. PLIP lists the hydrogen bonds, hydrophobic contacts, salt bridges and stacking in the pose so it can be compared with known structure-activity data; it takes the complex as one PDB file, so set Output format to PDB when that step is planned. MolProbity checks the protein geometry.
Native affinity accepts at most 128 atoms for its selected ligand; select Structure only for larger ligands within the hosted structure limit. Custom checkpoints are not supported.
Affinity outputs are intended for prioritization among related protein-small-molecule predictions and are not experimental binding measurements. Other complex types still receive structure and confidence outputs, but they do not receive the same affinity estimate. Memory use increases with the size and number of input chains, so long sequences and many chains can require substantially more resources. Covalent-bond constraints use standardized CCD atom names and are supported for canonical polymer residues and CCD ligand inputs; use the regular ligand input for custom small-molecule structures.
Each example is a public run that opens with its inputs, settings and results. The KRAS and transcription-factor runs predate the current release, so they repeat the run-level affinity on every sample row, and the ligand-free run shows placeholder affinity values of 0 and 0.5. Current runs attach affinity to rank 1 only and omit it when no ligand is scored.
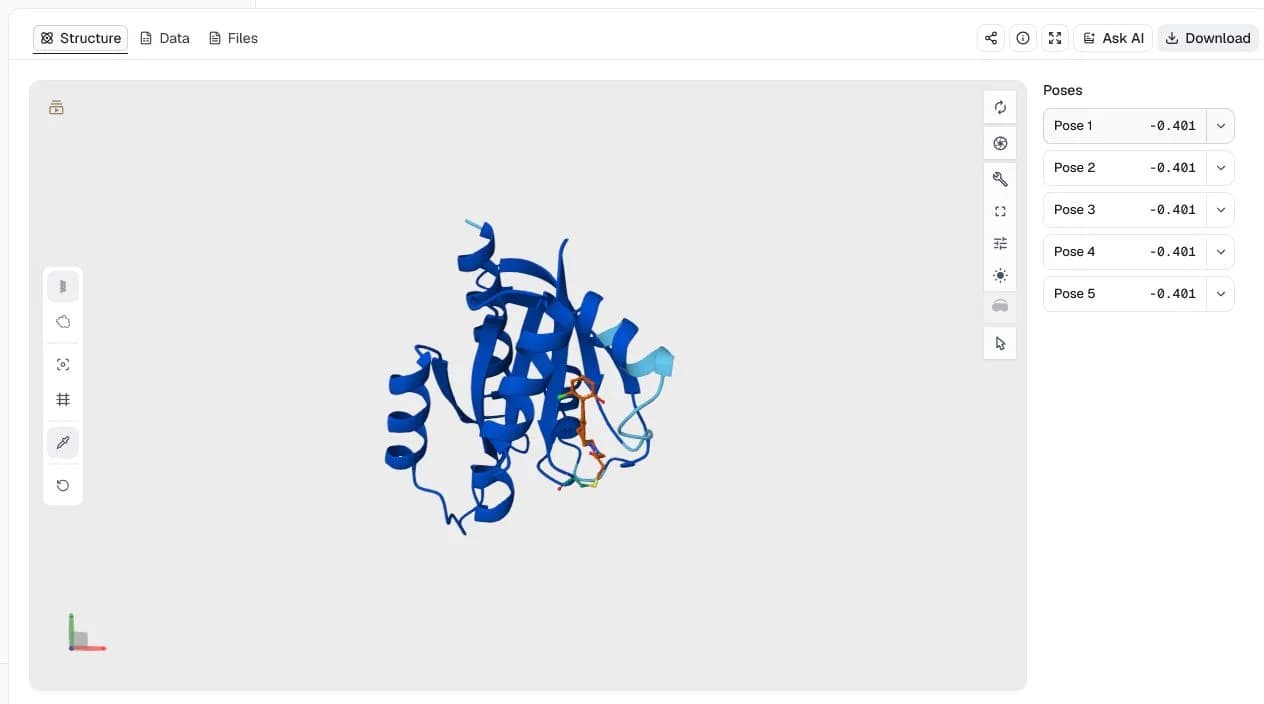
This protein-ligand run predicts the 168-residue KRAS G12C chain A with the CCD ligand U4U as chain B, joined by the covalent bond A:12:SG,B:1:C22 with Use constraint potentials on. It uses 5 samples, Generate MSA at Normal depth and a Step scale (temperature) of 1.638.
The five confidence_score values span only 0.961 to 0.965. Rank 1 scores 0.965, which is 0.8 times its complex_plddt of 0.961 plus 0.2 times its iptm of 0.979; protein_iptm is 0 because there is one protein chain. The affinity_pred_value of -0.401 (about 0.40 µM) and affinity_probability_binary of 0.950 describe this pose with the bond imposed, not covalent reactivity or measured potency.
This four-chain run combines two complementary 15-nucleotide DNA strands with two copies of an 89-residue transcription-factor construct, using 5 samples, Normal MSA depth and a step scale of 1.638. Rank 1 has iptm 0.913 and complex_iplddt 0.980, and all five samples fall between 0.950 and 0.956 on confidence_score. That consistency supports the assembly but not sequence-specific base contacts, and the affinity values are placeholders because there is no ligand.
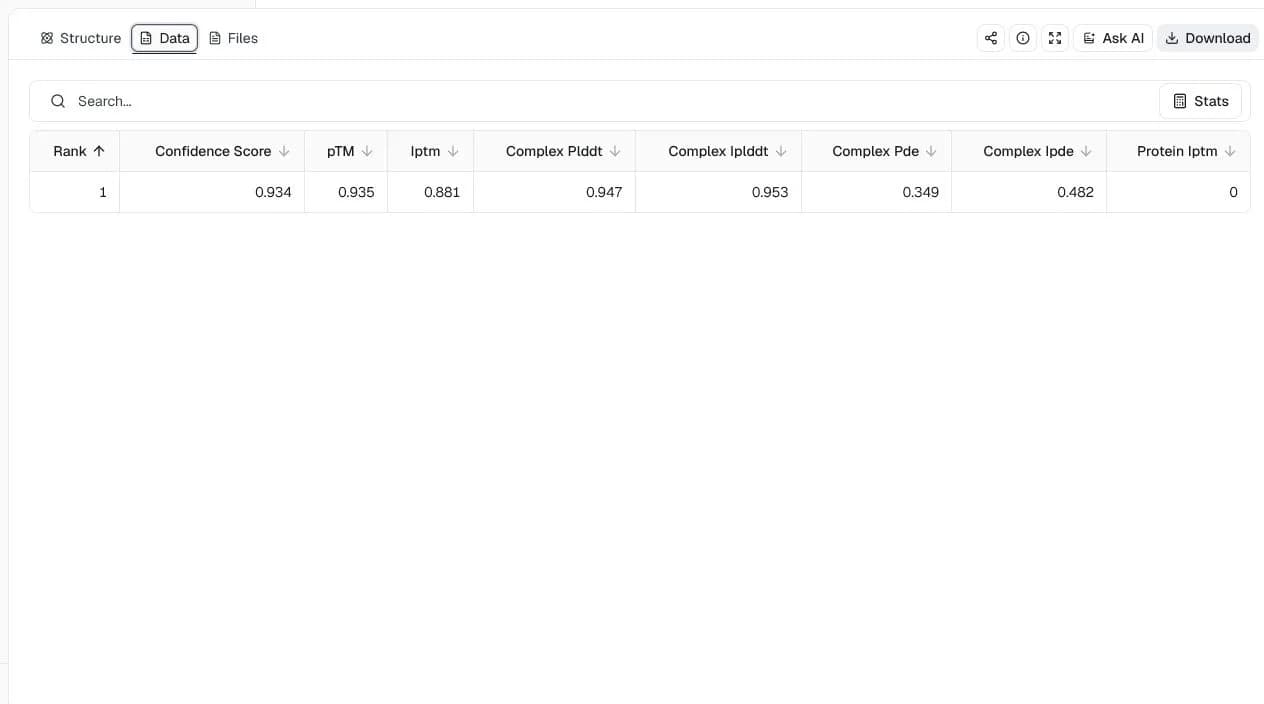
This protein-RNA run uses the 97-residue U1A RNA-recognition domain and the 21-nucleotide hairpin from PDB 1URN with default settings, and shows the current layout with no affinity columns. It reports confidence_score 0.934, iptm 0.881 and complex_plddt 0.947. Superposing the model on 1URN and measuring TM-score or RMSD tests the interface those scores describe.
jwohlwend/boltz. github.com/jwohlwend/boltz
Low-memory Boltz inference for biomolecular structure and affinity prediction

Structure and binding prediction for proteins, DNA, RNA and ligands.

Predict 3D structures for proteins, ligands, DNA, RNA, and multi-component complexes.

Predict controllable biomolecular structures for proteins, ligands, DNA, RNA, and complexes.

All-atom biomolecular structure prediction

Open-source AlphaFold3-based structure prediction for proteins, ligands, DNA, and RNA

Open-source biomolecular structure prediction with Protenix

Open-source structure prediction for proteins, nucleic acids, and ligands

Predict paired antibody variable-domain structures from heavy and light chain sequences.

Generate protein conformational ensembles from sequence or structure inputs.