Generate, score, and compare canonical DNA sequences with Carbon language models. Learn more
Input
Raw canonical DNA or FASTA input.
What is Carbon?
Carbon is a family of autoregressive genomic foundation models from Hugging Face Bio for DNA generation, sequence likelihood scoring, and reference-versus-alternate sequence comparison. It treats DNA as a language modeling problem, but uses a DNA-specific 6-mer tokenizer instead of ordinary text tokenization for bases.
ProteinIQ runs Carbon on canonical DNA sequences containing only A, C, G, and T. Ambiguity bases such as N, degenerate IUPAC codes, RNA U, and non-sequence annotations are not valid Carbon input.
Carbon is most useful when the question depends on learned genomic sequence context: extending a DNA sequence, ranking sequences by model likelihood, or asking whether an alternate sequence is more or less likely than a reference under the selected model. For deterministic sequence editing, use DNA mutator, DNA shuffle, or Reverse complement instead.
How to use Carbon online
Run Carbon online by pasting canonical DNA or uploading FASTA or text files, then choosing generation, scoring, or compare mode. ProteinIQ runs the selected Hugging Face Carbon checkpoint and returns generated DNA, likelihood scores, reference-versus-alternate deltas, spreadsheet data, and downloadable CSV or JSON files. FNS scoring also returns the full per-base probability distribution.
Inputs
| Input | Accepted values | Notes |
|---|---|---|
DNA sequence | Raw DNA, FASTA, .fa, .fasta, or .txt | Only uppercase or lowercase canonical DNA bases are accepted after normalization to A, C, G, and T. |
Reference sequence | Canonical DNA | Required in Compare mode through the dedicated reference input. |
Alternate sequence | Canonical DNA | Required in Compare mode through the dedicated alternate input. |
Generation and standard token scoring require at least 6 bp because each DNA token represents one non-overlapping 6-mer. FNS base-pair scoring accepts sequences from 1 bp and preserves partial final 6-mers through Carbon's native right-padding and length recovery. Sequences longer than the selected context window are scored or extended using the rightmost context segment. The maximum accepted sequence length is 786,432 bp.
Modes
| Mode | What it does | Typical use |
|---|---|---|
Generation | Extends the submitted DNA sequence by up to Max new bp. | Designing short continuations from a known genomic context or exploring model-preferred next bases. |
Score | Calculates model likelihood for each submitted sequence. | Ranking sequence candidates or checking whether edited sequences remain plausible under Carbon. |
Compare | Scores a reference and alternate sequence, then reports the alternate-minus-reference delta. | Variant-style analysis, motif perturbation checks, or comparing two candidate edits. |
In Compare mode, enter the sequences in the dedicated Reference sequence and Alternate sequence inputs. Their roles are explicit, so Carbon does not infer comparison order from unrelated inputs or settings.
Model choices
| Model | Best fit | Context behavior |
|---|---|---|
Carbon-500M | Fast drafts and lower-cost exploratory runs. | Smaller native context than the larger models. |
Carbon-3B | Default model for most Carbon jobs. | Flagship checkpoint with a 32,768-token native DNA context, about 196 kbp. |
Carbon-8B | Higher-capacity runs when runtime cost is acceptable. | Same 32,768-token native DNA context, with stronger long-context behavior when YaRN is enabled. |
Carbon uses one DNA token per 6 bases. A 32,768-token context is therefore about 196,608 bp before accounting for model tags and generation budget. YaRN long-context inference is available for Carbon-3B and Carbon-8B. Carbon-500M runs at its native 8,192-token context.
Settings
| Setting | Default | Description |
|---|---|---|
Mode | Generation | Selects generation, scoring, or comparison. |
Model | Carbon-3B | Chooses Carbon-500M, Carbon-3B, or Carbon-8B. |
Inference resolution | 6-mer token | Uses standard 6-mer inference or Carbon's FNS base-pair marginals. Base-pair mode provides nucleotide-resolved generation and scoring with additional runtime. |
Precision | bfloat16 | Inference precision. bfloat16 is the standard setting. float32 can be slower and requires more GPU memory. |
Species conditioning | None | Optionally adds one of Carbon's six documented taxonomic metadata tags: mammalian vertebrate, non-mammalian vertebrate, fungi, plant, protozoan, or invertebrate. FNS scoring accepts raw DNA only, so select None for base-pair score and compare jobs. |
Use YaRN | Off | Enables long-context RoPE scaling for models that support it. |
Max context (bp) | 6144 | Maximum DNA context passed to the model. Longer sequences use the rightmost window. Values are rounded to 6-mer boundaries. |
Max new bp | 30 | Maximum generated DNA length in generation mode. The generation budget shares the model context window with the input context. |
Sample | Off | Uses stochastic decoding when enabled. When off, generation is deterministic for the same model and context. |
Temperature | 1 | Sampling temperature used only when Sample is on. Higher values increase diversity. |
Top-k | 50 | Limits sampling to the top k candidate tokens when Sample is on. |
Top-p | 1 | Nucleus sampling cutoff when Sample is on. Lower values concentrate generation on higher-probability choices. |
Reverse-complement average | Off | In compare mode, averages forward and reverse-complement scores before calculating the delta. |
Batch size | 2 | Number of sequences scored per inference batch in score and compare modes. |
Seed | 0 | Random seed used only for sampled generation. |
Understanding Carbon results
Generation results
Generation mode returns one row per input sequence.
| Column | Meaning |
|---|---|
input_length_bp | Length of the submitted sequence. |
context_length_bp | Number of bases actually used as model context. If this is smaller than input_length_bp, the rightmost context window was used. |
max_new_bp | Requested generation limit in base pairs. |
generated_sequence | Newly generated DNA continuation. |
generated_length_bp | Length of the generated continuation. |
full_sequence | Context sequence plus generated continuation. |
do_sample, temperature, top_k, top_p | Decoding settings used for the run. |
inference_resolution | Whether generation used standard 6-mer token selection or FNS base-pair marginals. |
The result view shows every submitted sequence and highlights each generated continuation. Downloaded generation jobs also include carbon-generated-sequences.fasta, where each record contains the context and generated continuation together.
Score results
Score mode reports log likelihoods for each sequence.
| Column | Meaning |
|---|---|
sequence_length_bp | Original sequence length. |
scored_length_bp | Length actually scored after context trimming. Standard token scoring aligns to 6-mer boundaries; FNS scoring preserves every original base, including partial final 6-mers. |
mean_logp | Mean log probability over scored positions or tokens. Higher values indicate a sequence the model considers more likely. |
total_logp | Sum of log probabilities across the scored sequence. Total log probability becomes more negative as sequence length increases, so it should not be compared across very different lengths without care. |
score_count | Number of scored units. |
score_unit | 6mer_token for standard inference or base_pair for FNS inference. |
token_count | Backward-compatible token count for standard 6-mer scoring; empty for FNS base-pair scoring. |
scoring_method | Whether Carbon used model-provided base-pair scoring or token-level log likelihood. |
mean_logp is usually the most useful score for comparing sequences of similar length. It is not a calibrated biological effect size, binding score, pathogenicity probability, or expression measurement.
FNS score and compare jobs include one CSV and one JSON file per scored orientation. Each row reports the 1-based position, observed base, Carbon's A, T, C, and G marginal probabilities, the observed-base probability, and its unmodified log probability. A true zero probability is represented as -Infinity; ProteinIQ does not replace it with a numeric floor.
Because these complete per-position files are delivered with the job result, one FNS score or compare job can export at most 40,000 total scored positions. Reverse-complement comparison counts both orientations. Reduce Max context, shorten the inputs, or turn off reverse-complement averaging when a request exceeds that delivery limit. Standard 6-mer scoring retains the model context limits shown above.
Compare results
Compare mode returns one row for the reference-versus-alternate pair.
| Column | Meaning |
|---|---|
ref_mean_logp | Mean log probability for the reference sequence. |
var_mean_logp | Mean log probability for the alternate sequence. |
delta_mean_logp | var_mean_logp - ref_mean_logp. Positive values favor the alternate under the model. |
ref_total_logp | Total log probability for the reference sequence. |
var_total_logp | Total log probability for the alternate sequence. |
delta_total_logp | Alternate-minus-reference total log probability. |
ref_mean_logp_forward, var_mean_logp_forward, delta_mean_logp_forward | Forward-orientation component scores. When reverse-complement averaging is off, these match the main mean-log-probability columns. |
ref_mean_logp_reverse_complement, var_mean_logp_reverse_complement, delta_mean_logp_reverse_complement | Reverse-complement component scores returned when reverse-complement averaging is enabled. |
ref_total_logp_forward, var_total_logp_forward, delta_total_logp_forward | Forward-orientation total-log-probability component scores. |
ref_total_logp_reverse_complement, var_total_logp_reverse_complement, delta_total_logp_reverse_complement | Reverse-complement total-log-probability component scores returned when reverse-complement averaging is enabled. |
preferred_sequence | alternate when the alternate has higher mean log probability, otherwise reference. |
rev_comp_avg | Whether forward and reverse-complement orientations were averaged. |
For single-base or short edits in a fixed-length context, delta_mean_logp is the clearest comparison column. For insertions, deletions, or sequences of different length, inspect both mean and total deltas because length changes affect total log probability directly.
Downloaded files
| File | Included for | Contents |
|---|---|---|
carbon-results.csv | All modes | Spreadsheet-ready result rows. |
carbon-results.json | All modes | Full result rows in JSON format. |
carbon-generated-sequences.fasta | Generation mode | FASTA records containing the context plus generated continuation. |
carbon-fns-###-*-base-probabilities.csv | FNS score and compare | Per-base A, T, C, and G marginals plus observed-base probability and log probability. |
carbon-fns-###-*-base-probabilities.json | FNS score and compare | JSON form of the same per-base probability records. |
Carbon examples
TP53 coding-sequence continuation with FNS
This example uses the first 240 bp of the human TP53 coding sequence from NCBI RefSeq transcript NM_000546.6 to demonstrate nucleotide-resolved Carbon generation.
- Input:
NM_000546.6TP53 coding-sequence start, 240 bp - Non-default settings:
Inference resolution=Base pair (FNS)for nucleotide-resolved generation;Max context (bp)=240;Max new bp=60
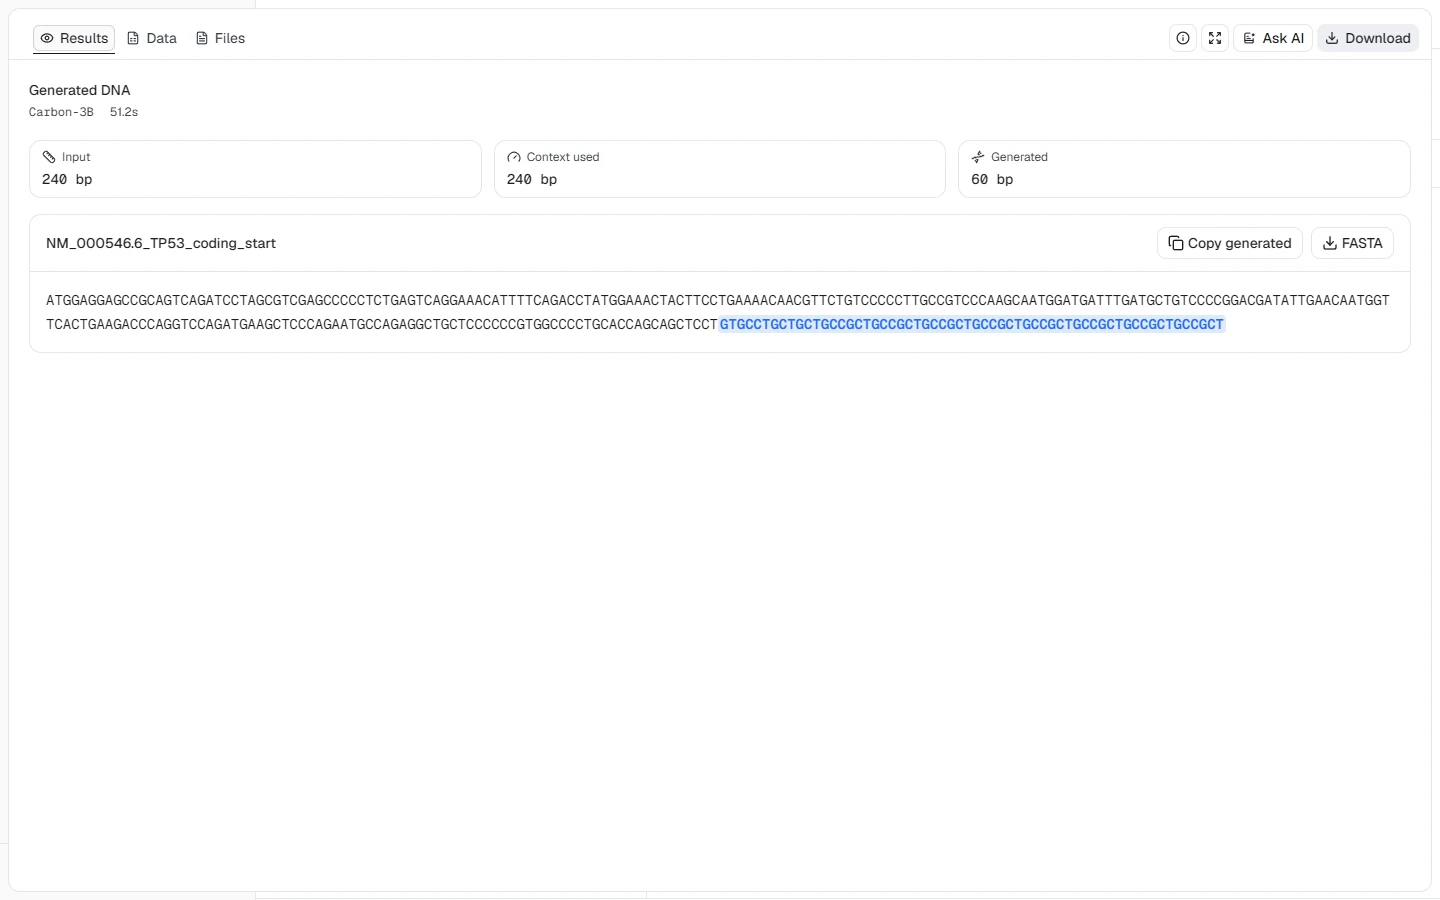
Carbon-3B used the full 240 bp context and returned a 60 bp continuation, highlighted in blue after the submitted sequence. The continuation is an autoregressive model output rather than a reconstruction of the known TP53 transcript, and its locally repetitive pattern should not be interpreted as evidence of gene function, expression, or biological viability.
Base-pair likelihood scoring across three bacteriophages
This batch example scores equal-length sequence starts from phiX174 (NC_001422.1), bacteriophage lambda (NC_001416.1), and M13 (NC_003287.2) in one Carbon run.
- Inputs: The first 180 bp from each of the three NCBI reference genomes
- Non-default settings:
Mode=Score;Model=Carbon-500M;Inference resolution=Base pair (FNS);Max context (bp)=180;Batch size=3
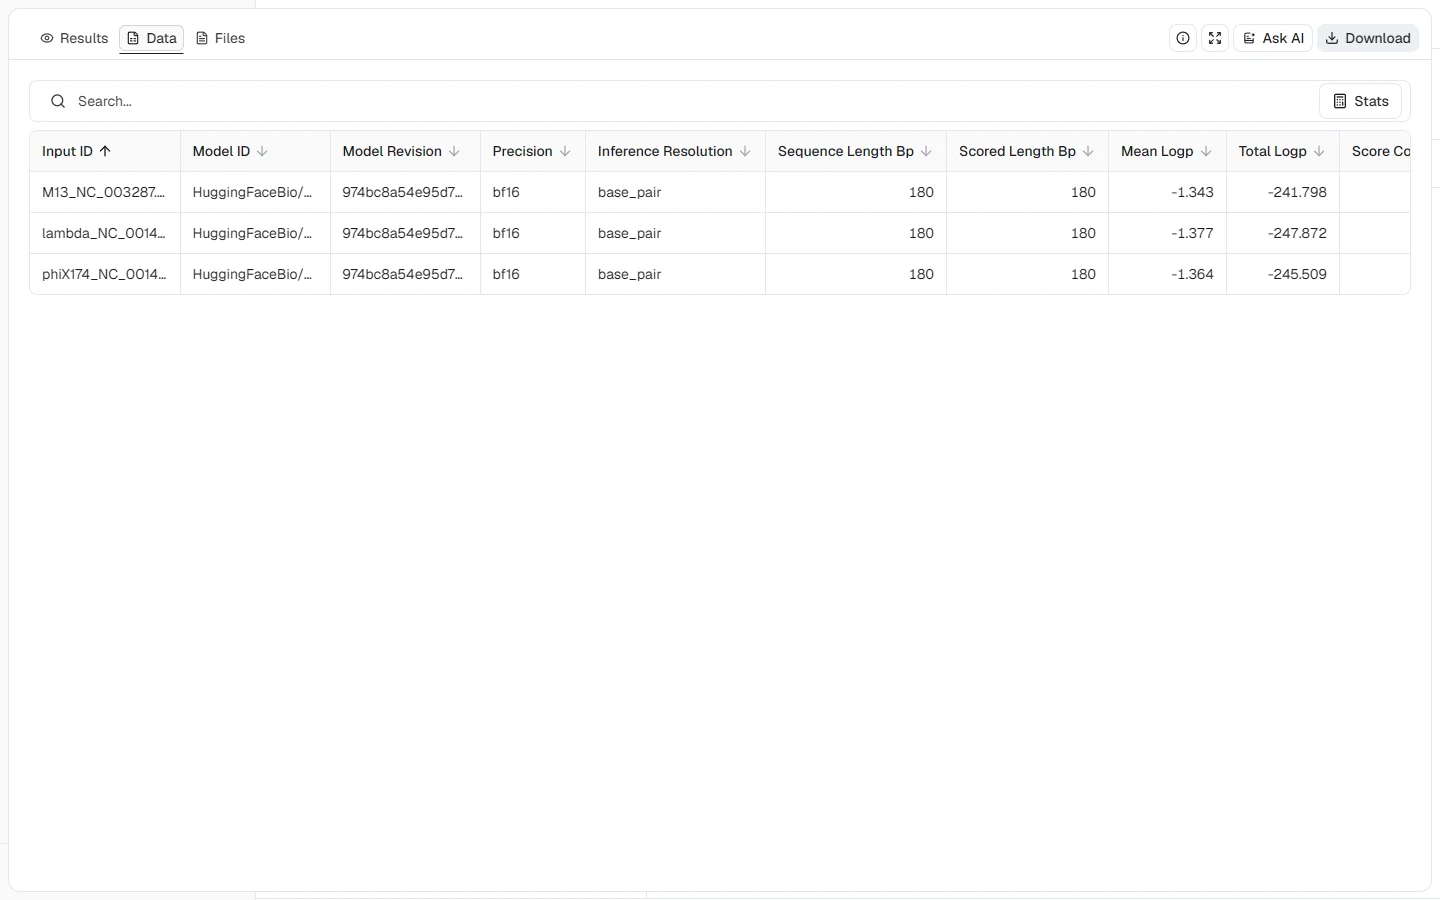
All three sequences were scored over 180 base pairs with fns_base_pair_log_likelihood. M13 has the highest mean log probability in this run at -1.343, followed by phiX174 at -1.364 and lambda at -1.377. Because the sequences have equal length and share the same model and settings, their mean log probabilities can be compared directly here. The ordering describes Carbon's learned sequence expectation; it does not measure phage fitness, infectivity, or host range.
HBB c.20A>T reference and alternate comparison
This example compares a 120 bp coding context from human HBB transcript NM_000518.5 with the c.20A>T alternate sequence, changing the reference GAG codon to GTG.
- Inputs: Matched 120 bp reference and alternate HBB coding sequences
- Non-default settings:
Mode=Compare;Model=Carbon-500M;Max context (bp)=120;Reverse-complement average= on
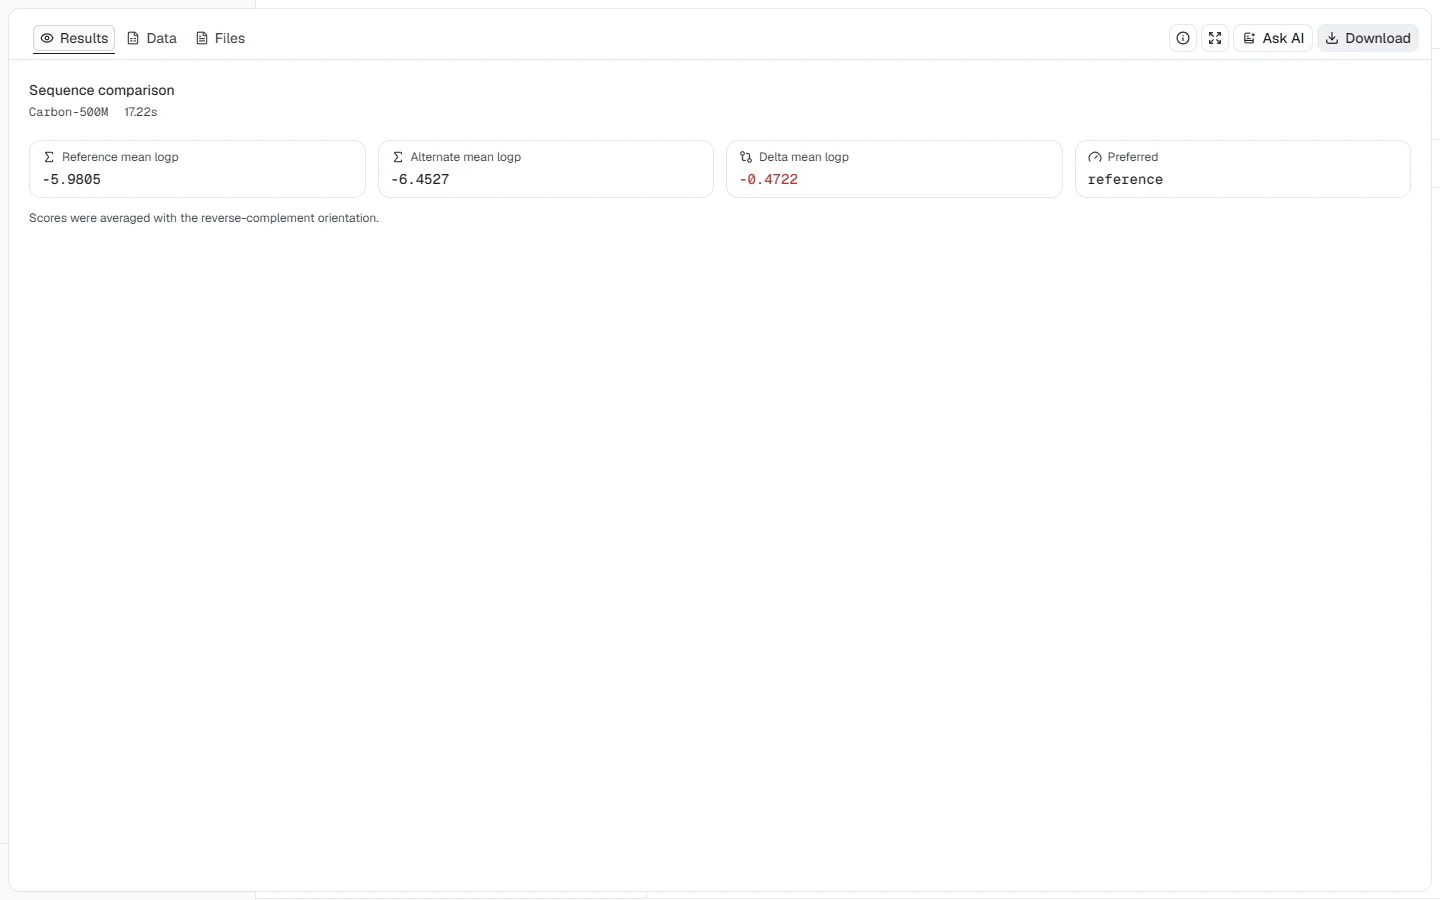
After averaging the forward and reverse-complement orientations, the reference mean log probability is -5.9805, the alternate mean log probability is -6.4527, and delta_mean_logp is -0.4722. Carbon therefore marks the reference as preferred under this checkpoint and context. This likelihood difference is not a calibrated pathogenicity score and cannot replace clinical annotation or experimental evidence.
How Carbon works
Carbon is a decoder-only Transformer model family trained on DNA and RNA sequence data. The key modeling choice is its hybrid tokenizer: English and metadata tokens use a text vocabulary, while DNA inside a <dna> block uses fixed non-overlapping 6-mers. ProteinIQ handles the DNA tag internally, so submitted DNA is tokenized in Carbon's DNA mode.
The 6-mer design improves efficiency because each model token represents 6 bp. It also creates practical constraints. Input must be canonical DNA, and standard token scoring and generation align context to 6-base boundaries. Carbon trims to the rightmost usable context when an input is longer than the selected window because autoregressive generation and scoring depend on the sequence immediately before the predicted bases. FNS scoring is different: Carbon right-pads a partial 6-mer internally, then returns probabilities only for the original bases, so no submitted base is discarded.
Likelihood scoring follows the usual causal language model interpretation: the model estimates how probable each next DNA token or base is given the previous context. Higher log probability means the sequence is more expected under the selected Carbon checkpoint and context, not necessarily more functional in an experiment.
FNS base-pair mode uses Carbon's native fns model revision. It marginalizes the 4,096 possible 6-mer outputs into six nucleotide distributions for generation and scoring. This gives nucleotide-resolved likelihoods while retaining Carbon's 6-mer context efficiency. Standard 6-mer mode remains the default and is faster.
Species conditioning prepends Carbon's documented taxonomic metadata token before the DNA tag. It is optional and does not change existing unconditioned runs. It is appropriate only when the submitted context has a known broad taxonomic group; it does not identify species or validate taxonomy.
YaRN extends the rotary-position context used by the model. It is useful for long genomic contexts, but longer windows increase runtime and memory use, and very long extrapolated contexts can reduce retrieval quality. For short sequence scoring or generation, the native context is usually easier to interpret.
When to use Carbon vs alternatives
Carbon fits learned DNA sequence modeling tasks: generation, likelihood ranking, and zero-shot comparison of reference and alternate DNA sequences. It is not a multiple sequence alignment tool, variant annotation database, or wet-lab validation substitute.
Use AlphaGenome when the goal is variant effect prediction against genomic functional tracks rather than model likelihood. Use DNA to Protein Converter for translation, DNA to RNA converter for transcription, and Random DNA when a random control sequence is needed without learned genomic context.
Related tools
CpG Island Finder
Identify CpG islands in DNA sequences using the Gardiner-Garden and Frommer criteria. Analyze GC content, CpG density, and observed/expected ratios.
GC content calculator
Calculate GC content, GC/AT skew, melting temperature, and CpG islands for DNA/RNA sequences, with a sliding-window GC plot. Analyze individual sequences or get combined statistics.
DNA ligation calculator
Calculate insert DNA mass for a target insert:vector molar ratio, compare common ratios, and optionally convert DNA stock concentrations into pipetting volumes.
Oligo analyzer
Analyze unmodified DNA oligos with Primer3 thermodynamic Tm, hairpin, self-dimer, heterodimer, physical, and OD260 calculations.
ORF Finder
Find open reading frames in DNA with the native NCBI ORFfinder search, translations, coordinates, and output files.
AbLang
Restore missing antibody residues, generate 768-dimensional sequence or residue representations, and calculate amino-acid likelihood scores with the original AbLang heavy- and light-chain models.
DockQ
Assess docking model quality by comparing predicted complexes against native references. DockQ v2.1.3 supports protein, nucleic-acid, and supported small-molecule interfaces with native metrics.
Prot2Prop
Predict multiple protein developability properties from amino-acid sequences using a multitask ProstT5 adapter.
CANYA
Predict protein aggregation nucleation propensity from amino acid sequences using the Lehner Lab CANYA neural network.
IPC 2.0 (isoelectric point calculator)
Isoelectric Point Calculator 2.0 - Predict protein/peptide isoelectric point (pI) using 18+ validated pKa scales, SVR models, and deep learning. Supports proteins, peptides, and comprehensive analysis.