ESM-C
Generate protein embeddings with ESM-C.
Generate protein embeddings with ESM-C.
ESM-C (ESM Cambrian) is a family of protein language models that turn an amino acid sequence into a numerical representation. Each residue becomes a high-dimensional vector that captures evolutionary, structural, and functional context, learned entirely from sequence with no alignments, templates, or 3D supervision.
The family comes in three sizes, and they trade accuracy for speed and memory:
| Variant | Parameters | Layers | Embedding dimension |
|---|---|---|---|
| ESMC-300M | 300M | 30 | 960 |
| ESMC-600M | 600M | 36 | 1152 |
| ESMC-6B | 6B | 80 | 2560 |
The 300M model is fast and fits most embedding work. The 6B model produces the richest representations and runs on larger GPU memory. ESM-C was designed to match or beat older ESM-2 models at a given parameter count, so a 600M ESM-C embedding often carries more signal than a similarly sized ESM-2 embedding.
Paste one or more protein sequences into ProteinIQ, pick a model size, and get back embedding files in NumPy format ready to load in Python. Input can be FASTA or raw single-letter sequence, up to 50 sequences per job. The default run returns final-layer per-token embeddings and a mean-pooled vector per sequence; forward-pass logits and a selected hidden layer are optional.
For masked substitution scores, residue entropy and mutation heatmaps, use ESM-C Mutation Scoring. Unmasked embedding logits are not mutation scores.
ESM-C uses the current MIT-licensed Biohub code and pinned checkpoints. The September 2026 update replaces the retired Biohub Transformers fork used for older embedding jobs. Embedding controls and file formats remain available, but new embeddings use the checkpoint revisions recorded in their metadata. Regenerate embeddings with one model revision before comparing them.
A job costs 30 credits, including the selected output files. Model size, sequence count within the accepted limits, and output choices do not currently change that price. The exact quote is calculated before submission.
| Input | Description |
|---|---|
Protein | FASTA, raw sequence text, or fetched from RCSB. Up to 50 sequences, 2,046 sequence tokens each, 20,000 tokens total. |
| Uploaded file | .fasta, .fa, .fas or .txt; up to 10 MiB per file. |
The tokenizer accepts the 20 standard amino acids plus X, B, U, Z, and O. It also supports . and - gap tokens and | as a chain break. Other characters are rejected rather than dropped or replaced.
| Parameter | Type | Default | Description |
|---|---|---|---|
Model variant | enum | ESMC-300M | ESMC-300M, ESMC-600M, or ESMC-6B; larger models require more memory and runtime. |
Hidden layer | integer | -1 | Layer saved when Include hidden states is enabled; -1 uses the final layer, otherwise accepts 0 to 30 for 300M, 0 to 36 for 600M, or 0 to 80 for 6B. |
Include per-token embeddings | boolean | true | One final-layer vector per sequence token. |
Include mean-pooled embeddings | boolean | true | One vector per sequence, averaged across final-layer sequence-token embeddings. |
Include sequence logits | boolean | false | Unmasked forward-pass scores over the vocabulary; increases output size. |
Include hidden states | boolean | false | Saves the selected layer's token matrix separately; when per-token embeddings are also enabled, a non-final layer avoids returning the same matrix twice. |
At least one output must remain selected.
| File | Format | Shape | Contents |
|---|---|---|---|
*_per_residue_embeddings.npy | NPY | (L, D) | One final-layer embedding row per input token, where L is token count and D is the model's embedding dimension. |
*_mean_pooled_embedding.npy | NPY | (D,) | Sequence-level vector, the mean of all final-layer token embeddings. |
*_selected_hidden_layer.npy | NPY | (L, D) | The chosen layer's token matrix, written only when hidden states are requested. |
*_logits.npz | NPZ | (L, 64) | Compressed archive with logits, input token_ids, sequence_tokens, and ordered vocab_tokens. |
Every tensor file reports the exact model revision used for the run. Logits archives also contain model_variant and model_revision arrays. Filenames are prefixed with the sequence index and label, so repeated labels remain distinct in a multi-sequence job.
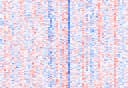
The Heatmap tab previews per-token embeddings when that output is enabled. The Data tab lists every processed sequence, its token count, model revision, dimensions, and selected layer, including runs that request only mean embeddings, hidden states, or logits. The Files tab contains all requested tensor files. The Run log records the model revision, output choices, sequence counts, and run outcome. Disabled tensor outputs are omitted.
ESM-C is a transformer trained with masked language modeling. During training, residues are hidden at random and the model predicts them from surrounding context. To do that well it has to internalize the statistics of real proteins: which residues co-vary, which positions tolerate substitution, which patterns signal a binding site or a buried core. Those learned patterns are what the embeddings encode.
The model runs the full sequence through its attention layers and the activations at each layer become the embeddings. Earlier layers tend to hold more local, sequence-level features; later layers hold more abstract, context-rich representations, which is why the final layer is the default choice for most downstream tasks.
The optional logits are the model's unnormalized vocabulary scores from one forward pass over the submitted, unmasked sequence. They are useful for inspecting model preferences and building custom analyses, but they are not leave-one-out mutation scores. Zero-shot mutation scoring requires a separate masked pass at each evaluated position.
Embeddings are features, not answers. Their value comes from how they cluster and compare.
A practical workflow: precompute mean-pooled embeddings for a protein library, then train a small classifier or regressor on top instead of fine-tuning the language model. This transfer-learning pattern is where ESM-C embeddings earn their cost, since a lightweight head on good embeddings frequently beats a model trained on raw sequence.
Both are sequence-only protein language models, so the choice is about efficiency and representation quality rather than a different kind of output. ESM-C is the newer family and delivers stronger embeddings per parameter, so ESMC-300M is a reasonable default where ESM-2 650M was the old habit. Pick ESMC-6B when representation quality matters more than runtime and the larger GPU is available.
For the older family, use ESM-2. When the goal is a 3D structure rather than embeddings, the same language model backbone powers ESMFold. For inverse folding, where a structure is given and a sequence is predicted, use ESM-IF1.

Predict non-germline residues and generate embeddings for paired or unpaired antibody sequences.

Analyze protein sequences and generate embeddings.

Bidirectional translation between protein sequences and 3Di structural tokens

Score amino acid substitutions with masked protein language models.

Restore residues and generate antibody-specific representations or likelihood scores.

Predict intrinsically disordered regions and per-residue disorder probabilities from protein sequences.

Cluster MSAs to predict alternative protein conformations with AlphaFold2

Predict protein aggregation nucleation propensity from amino acid sequences.

Predict MMP cleavage z-scores, evaluate substrates, and generate conditional peptides.

Calculate protein and peptide pI values using validated pKa scales and sequence models.